Article · October 24, 2026
AI Providers Can’t Rent Search Forever
Search infrastructure is becoming a competitive layer in AI. An analysis of indexes, provider dependencies and the implications for SEO and GEO measurement.
In this article
Search infrastructure is becoming a competitive layer in AI - and Google’s restrictions on automated SERP access make that dependency increasingly visible.
We spend a lot of time comparing AI models.
Which model reasons better? Which one is faster? Which one has the larger context window? Which produces better answers?
But underneath those models sits another competitive layer that may become just as important:
search infrastructure.
Crawlers. Indexes. Retrieval systems. Ranking pipelines. Search APIs. Live fetching. Structured data sources.
For an AI product that needs current information from the web, these are not implementation details.
They determine what can be discovered, how fresh it is, how quickly it can be retrieved and ultimately what information reaches the model.
And recent changes around Google Search make the strategic value of owning more of that infrastructure much easier to see.
Google is making automated SERP collection harder
First, an important distinction.
Google officially states that automated queries to Google Search - including scraping search results for rank checking - violate its spam policies and Terms of Service.
What Google does not officially say is:
We are deliberately returning fake search results to SEO tools.
That part comes from observations by companies operating large-scale SERP collection infrastructure.
And those observations are becoming increasingly interesting.
SISTRIX reports that Google has progressively complicated search-result collection since 2025.
Among the changes it documents:
- the removal of the ability to retrieve 100 results with a single query
- search-result lists ending before position 100
- broad use of internal
/gotoredirect URLs - and, since September 2026, result sets that can differ substantially from normal search results
According to SISTRIX, these divergent SERPs can look genuine while containing different websites, requiring additional validation before the data can be trusted.
Ahrefs describes the same phenomenon more aggressively.
In an October 22, 2026 update, Ahrefs called it “poisoning” of search results and said that, depending on the data provider, it was seeing approximately 5–20% of results affected.
That wording belongs to Ahrefs, not Google.
The underlying observation, however, matters.
SERP providers increasingly cannot assume that one automated request will return the same result set that a normal user would see.
There is another infrastructure change too.
DataForSEO reports that Google has widely rolled out google.com/goto intermediary URLs across organic results. Instead of exposing the destination URL directly, the actual target needs to be discovered by following the redirect.
DataForSEO says it had to build infrastructure to resolve those URLs and currently resolves direct destinations for 99.99% of affected organic SERPs.
SISTRIX makes the business impact clear: resolving those masked URLs means additional requests, additional processing and additional cost.
None of this makes SERP collection impossible.
But it makes it more expensive, less predictable and operationally more complex.
And that matters far beyond SEO tooling.
Search access is a dependency
Imagine building an AI product whose usefulness depends on current web information.
You need:
- broad web coverage
- fresh documents
- predictable latency
- reliable URLs
- granular content extraction
- ranking and reranking
- structured metadata
- strong availability
- predictable cost
If your entire retrieval layer depends on another company’s search engine, you inherit that company’s policies, technical changes, pricing, latency and access restrictions.
That does not mean third-party search APIs are bad.
It means they are a dependency.
For small applications, that dependency may be perfectly rational.
For companies trying to build foundational AI search products, it becomes strategic.
Perplexity has already crossed that line
Perplexity provides probably the clearest example.
Its engineering team has described why existing search APIs were insufficient for an AI-first retrieval system.
According to Perplexity, traditional APIs were too expensive, too slow, too stale or insufficiently granular for the retrieval patterns required by AI systems.
Its conclusion was straightforward:
it needed dedicated search infrastructure.
This is no longer a small crawler experiment.
Perplexity says its search index tracks more than 200 billion unique URLs and that it has built an exabyte-scale crawling and indexing system.
Its architecture combines:
- distributed indexing
- lexical retrieval
- semantic retrieval
- multi-stage ranking
- document-level retrieval
- sub-document retrieval
- machine-learning-driven crawl prioritization
- freshness optimization
The important point is not whether Perplexity has recreated Google.
The cited engineering account does not establish that it has.
The point is that controlling the retrieval layer became strategically important enough to justify building the infrastructure.
OpenAI is also building its own search layer
OpenAI gives us another useful example, but the evidence needs to be interpreted carefully.
OpenAI operates OAI-SearchBot, a crawler specifically associated with search.
Its documentation says OAI-SearchBot is used to surface websites in ChatGPT Search and that blocking the crawler can prevent content from appearing in ChatGPT search answers.
That is already a different role from GPTBot, which relates to model development.
OpenAI also now explicitly documents an OpenAI search index.
For HIPAA-eligible ChatGPT workspaces, OpenAI says Web Search and Deep Research use information from OpenAI’s own search index and do not send queries to third-party search providers such as Bing.
Elsewhere, OpenAI states that ChatGPT Search can still partner with external search providers. Its current documentation lists Microsoft among those providers.
That distinction is important.
The defensible conclusion is not:
OpenAI has replaced Bing with its own universal search engine.
The evidence supports something more interesting:
OpenAI can operate both proprietary and external search infrastructure depending on the product and environment.
That is a hybrid architecture.
OpenAI has also described maintaining an independent web index for another purpose: validating whether URLs are already publicly known before an agent automatically accesses them.
That is not the same thing as a search ranking index, but it is further evidence that maintaining web-scale discovery infrastructure has value beyond generating blue-link results.
Anthropic shows another version of the same architecture
Anthropic also separates its web-access systems.
Its current crawler documentation lists three distinct agents:
- ClaudeBot for model development.
- Claude-User for user-initiated retrieval.
- Claude-SearchBot for search.
Anthropic says Claude-SearchBot navigates the web to improve search-result quality and that blocking it prevents Anthropic from indexing content for search optimization.
Again, crawling does not automatically mean that Anthropic operates a complete independent Google-style search index.
We should not infer more than the documentation supports.
At the same time, Anthropic also uses external search infrastructure.
Google Cloud’s documentation for Claude web search currently lists Brave Search as the third-party search provider used by Anthropic in that environment.
So once again, the architecture appears more nuanced than:
one AI provider = one search engine.
It can involve proprietary crawling plus external search providers plus direct fetching.
Brave makes independence itself a product
Brave is strategically relevant here because its Search API is built on its own web index.
Brave explicitly says that its API does not fall back to Google or Bing and that results come from an independently crawled and ranked index.
That proposition becomes more valuable when access to other search engines becomes less predictable.
Brave is effectively selling something larger than search results.
It is selling independence from upstream search-engine access.
That is an interesting infrastructure position in an AI ecosystem where agents may execute dozens of search requests during a single task.
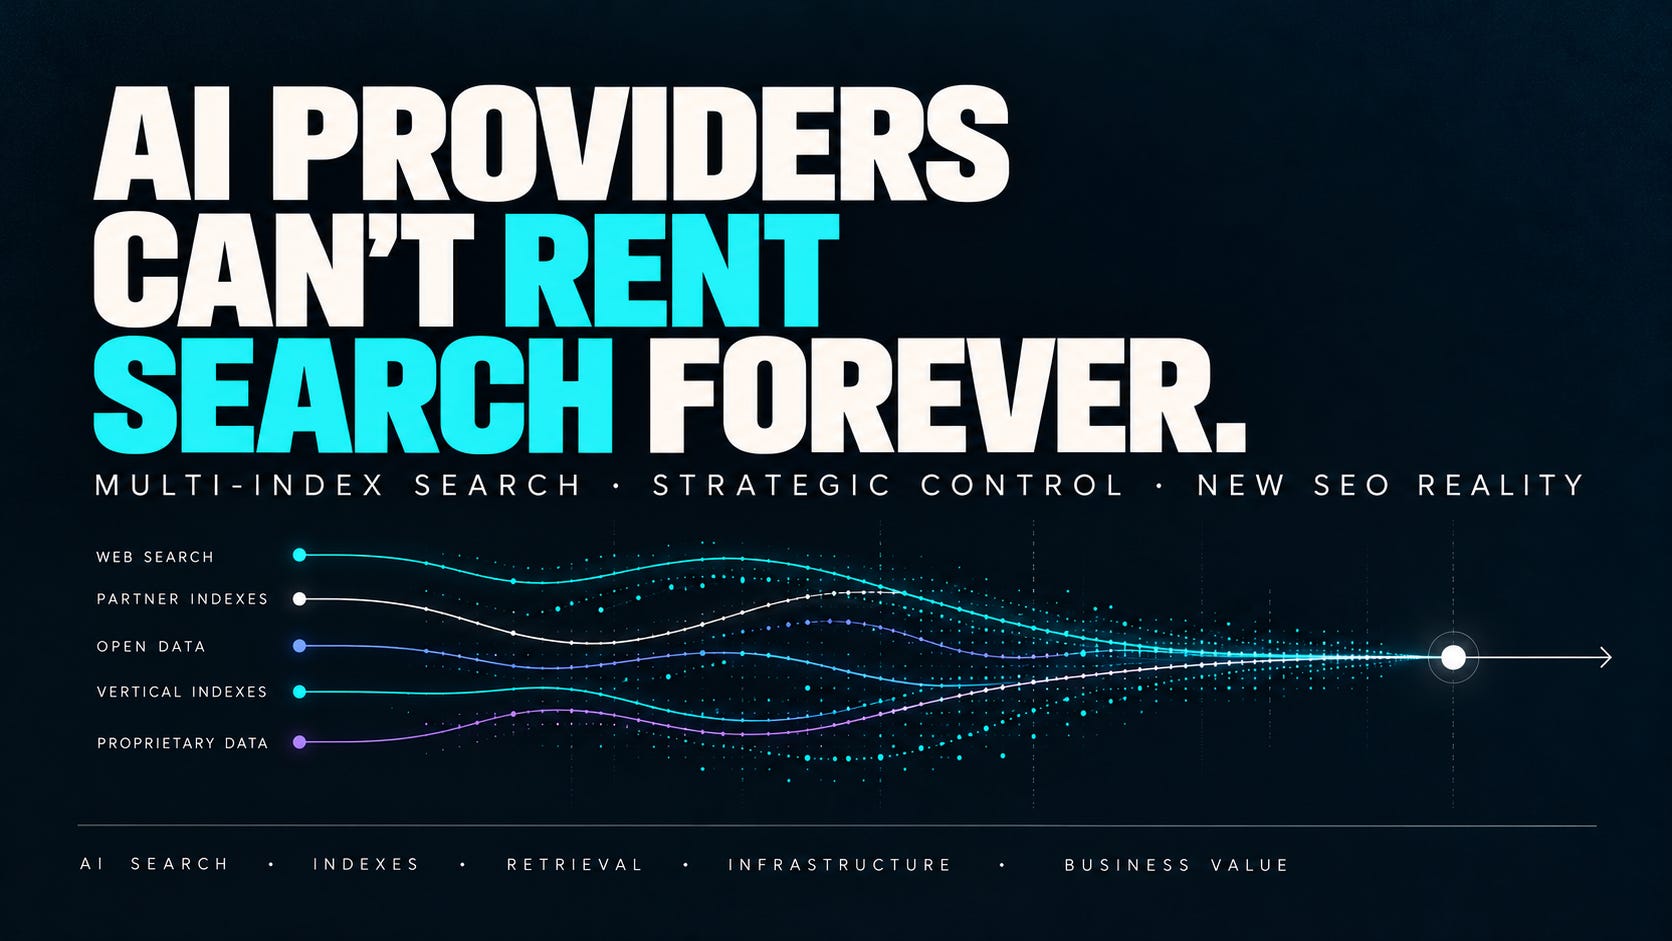
AI Search is becoming multi-index
This leads to what I think is the more important SEO/GEO conclusion.
We should stop imagining AI Search as:
LLM + Google results.
The emerging architecture looks more like:
- proprietary crawler
- proprietary index
- Bing
- Brave
- external providers
- live page fetching
- product feeds
- structured databases
- specialized vertical sources
- retrieval and reranking layers
Different products can combine these components differently.
Even the same provider may use different architectures depending on the product, geography, enterprise configuration or compliance requirements.
That means AI Search is increasingly becoming multi-index.
Not because every AI company is trying to recreate Google.
But because controlling more of the discovery and retrieval stack gives providers strategic advantages.
Why owning search infrastructure matters
There are several obvious reasons.
1. Freshness
AI systems answering current questions need recently updated information.
A provider controlling its own crawler and refresh scheduling can decide which documents deserve frequent recrawling rather than accepting another API’s update cadence.
2. Latency
Search is often one step inside a much longer agent workflow.
When an agent performs many searches, hundreds of milliseconds become meaningful.
Additional API hops, redirects or retrieval layers can accumulate quickly.
3. Retrieval quality
Traditional search engines were optimized primarily around returning results to humans.
AI systems need something different.
They may need:
- smaller content spans
- semantically meaningful passages
- entity-level information
- structured attributes
- high-recall candidate retrieval followed by aggressive reranking
Perplexity explicitly describes retrieving and ranking information at both document and sub-document level for this reason.
4. Cost
High-volume search API usage becomes expensive quickly.
At AI scale, owning infrastructure can move from an engineering luxury to an economic decision.
5. Availability and policy risk
An upstream provider can change:
- APIs
- pricing
- parameters
- rate limits
- anti-automation mechanisms
- result presentation
- access policies
Google’s recent changes are a good demonstration of this dependency risk.
Again, they do not prove why AI companies started building indexes.
But they strengthen the argument for doing so.
What this means for SEO and GEO
This architecture changes how I would approach visibility measurement.
A Google ranking is useful.
But it is not a universal proxy for AI visibility.
A URL could:
- rank well in Google
- be poorly represented in another index
- be frequently crawled by an AI bot
- never be retrieved for relevant prompts
- be retrieved but not cited
- be cited but receive no referral traffic
- receive AI traffic but generate no incremental business value
Those are different stages.
They should remain different in our measurement models.
For enterprise SEO/GEO, I would separate:
Crawling → indexing → retrieval → ranking → citation → referral → transaction
And I would monitor the relevant crawler families separately.
For OpenAI, for example:
OAI-SearchBot is not the same signal as GPTBot.
For Anthropic:
Claude-SearchBot is not the same signal as ClaudeBot.
A rise in crawler activity therefore does not automatically mean improved AI visibility.
And improved AI visibility does not automatically mean incremental revenue.
The operating model should change too
The long-term opportunity is not simply another AI visibility dashboard.
I would rather connect several analytical layers into one operating model.
For each URL, product, merchant, category or market:
- Crawler layer
- Which bots accessed it?
- What status codes did they receive?
- Was access blocked by robots.txt, CDN rules or WAF configuration?
- Search layer
- Is the URL indexed?
- Where does it rank?
- How much conventional search demand exists?
- AI Search layer
- Is the entity mentioned?
- Is the URL cited?
- Across which prompts and scenarios?
- Does it receive AI referrals?
- Business layer
- Do those referrals convert?
- Do they generate orders, GMV, revenue or margin?
- Catalogue layer
- Which product, offer, merchant, category and market does the URL represent?
That gives us a much stronger Single Source of Truth.
Not because it magically proves causality.
It does not.
But because it allows teams to diagnose problems, identify anomalies and prioritize engineering and content work using business context.
What the evidence does not prove
There are several claims I would explicitly avoid.
Google’s SERP restrictions do not prove that OpenAI, Anthropic or Perplexity built their crawling infrastructure because of Google.
Those investments started for multiple reasons and on different timelines.
Claude-SearchBot does not prove that Anthropic runs a completely independent global search engine.
OAI-SearchBot does not mean every ChatGPT Search answer comes entirely from OpenAI’s own index.
A proprietary crawler does not automatically mean full index independence.
And more crawling does not mean more citations.
The evidence supports a narrower but strategically stronger conclusion:
AI providers increasingly need more control over discovery, indexing and retrieval.
- That can mean owning an index.
- It can mean combining several indexes.
- It can mean working with independent providers such as Brave.
- Most likely, it means all of these at the same time.
The bigger competition
We tend to frame the AI race as:
model vs. model.
I think that framing is becoming incomplete.
The next competitive layer may increasingly be:
- index vs. index
- retrieval stack vs. retrieval stack
- crawler infrastructure vs. crawler infrastructure
- data ecosystem vs. data ecosystem
Models still matter enormously.
But a model can only reason over the information that reaches it.
And that makes search infrastructure part of the product.
For SEO and GEO teams, this means the search ecosystem is becoming more fragmented, not less.
There may no longer be one index we can optimize for and use as a proxy for everything else.
The future looks much more like a network of crawlers, indexes, feeds, APIs and retrieval systems.
AI Search is becoming multi-index.
And that changes both how we optimize and how we measure.
References
- OpenAI Crawlers — developers.openai.com/api/docs/bots — Defines OAI-SearchBot and its role in ChatGPT Search.
- OpenAI Search Index / HIPAA — help.openai.com/en/articles/20001069 — Documents use of OpenAI’s own search index in HIPAA-eligible environments.
- Searching the web with ChatGPT — help.openai.com/en/articles/9237897 — Documents ChatGPT’s use of external search providers.
- OpenAI: AI agent link safety — openai.com/index/ai-agent-link-safety — Describes an independent web index used to validate public URLs.
- Anthropic Crawlers — support.claude.com/en/articles/8896518 — Defines ClaudeBot, Claude-User and Claude-SearchBot.
- Claude Web Search on Google Cloud — docs.cloud.google.com/gemini-enterprise-agent-platform/models/partner-models/claude/web-search — Lists Brave Search as the third-party provider in this environment.
- Perplexity: Architecting and Evaluating an AI-First Search API — perplexity.ai/hub/blog/architecting-and-evaluating-an-ai-first-search-api — Details Perplexity’s crawling, indexing, retrieval and ranking infrastructure.
- Brave Search API — brave.com/search/api — Documents Brave’s independent crawler and index.
- Google Search Spam Policies — developers.google.com/search/docs/essentials/spam-policies — Defines Google’s policy toward automated queries and rank-checking traffic.
- Ahrefs: Google SERP Data Update — ahrefs.com/blog/serp-data-update — Reports divergent results affecting SERP providers.
- SISTRIX: Why Google ranking data collection is changing — sistrix.com/support/google-ranking-data-collection — Documents divergent results,
/gotoredirects and reduced access to deeper SERPs. - DataForSEO: Google’s /goto rollout — dataforseo.com/update/googles-goto-rollout — Documents Google redirect URLs and DataForSEO’s resolution layer.
Your perspective matters
What are you seeing in practice?
Which of these changes is already affecting your team? Share your experience on LinkedIn or read the related note on Substack.